HOOSHWARE
Live
LIVE
0
LIVEConnecting to Hooshware intelligence•
00:00:00
AI Heat
LOW
Monitoring0 sources

Hooshware

ESTABLISHING NEURAL LINK...
Back to News Radar
Smaller KV cache
Model Release

Smaller KV cache

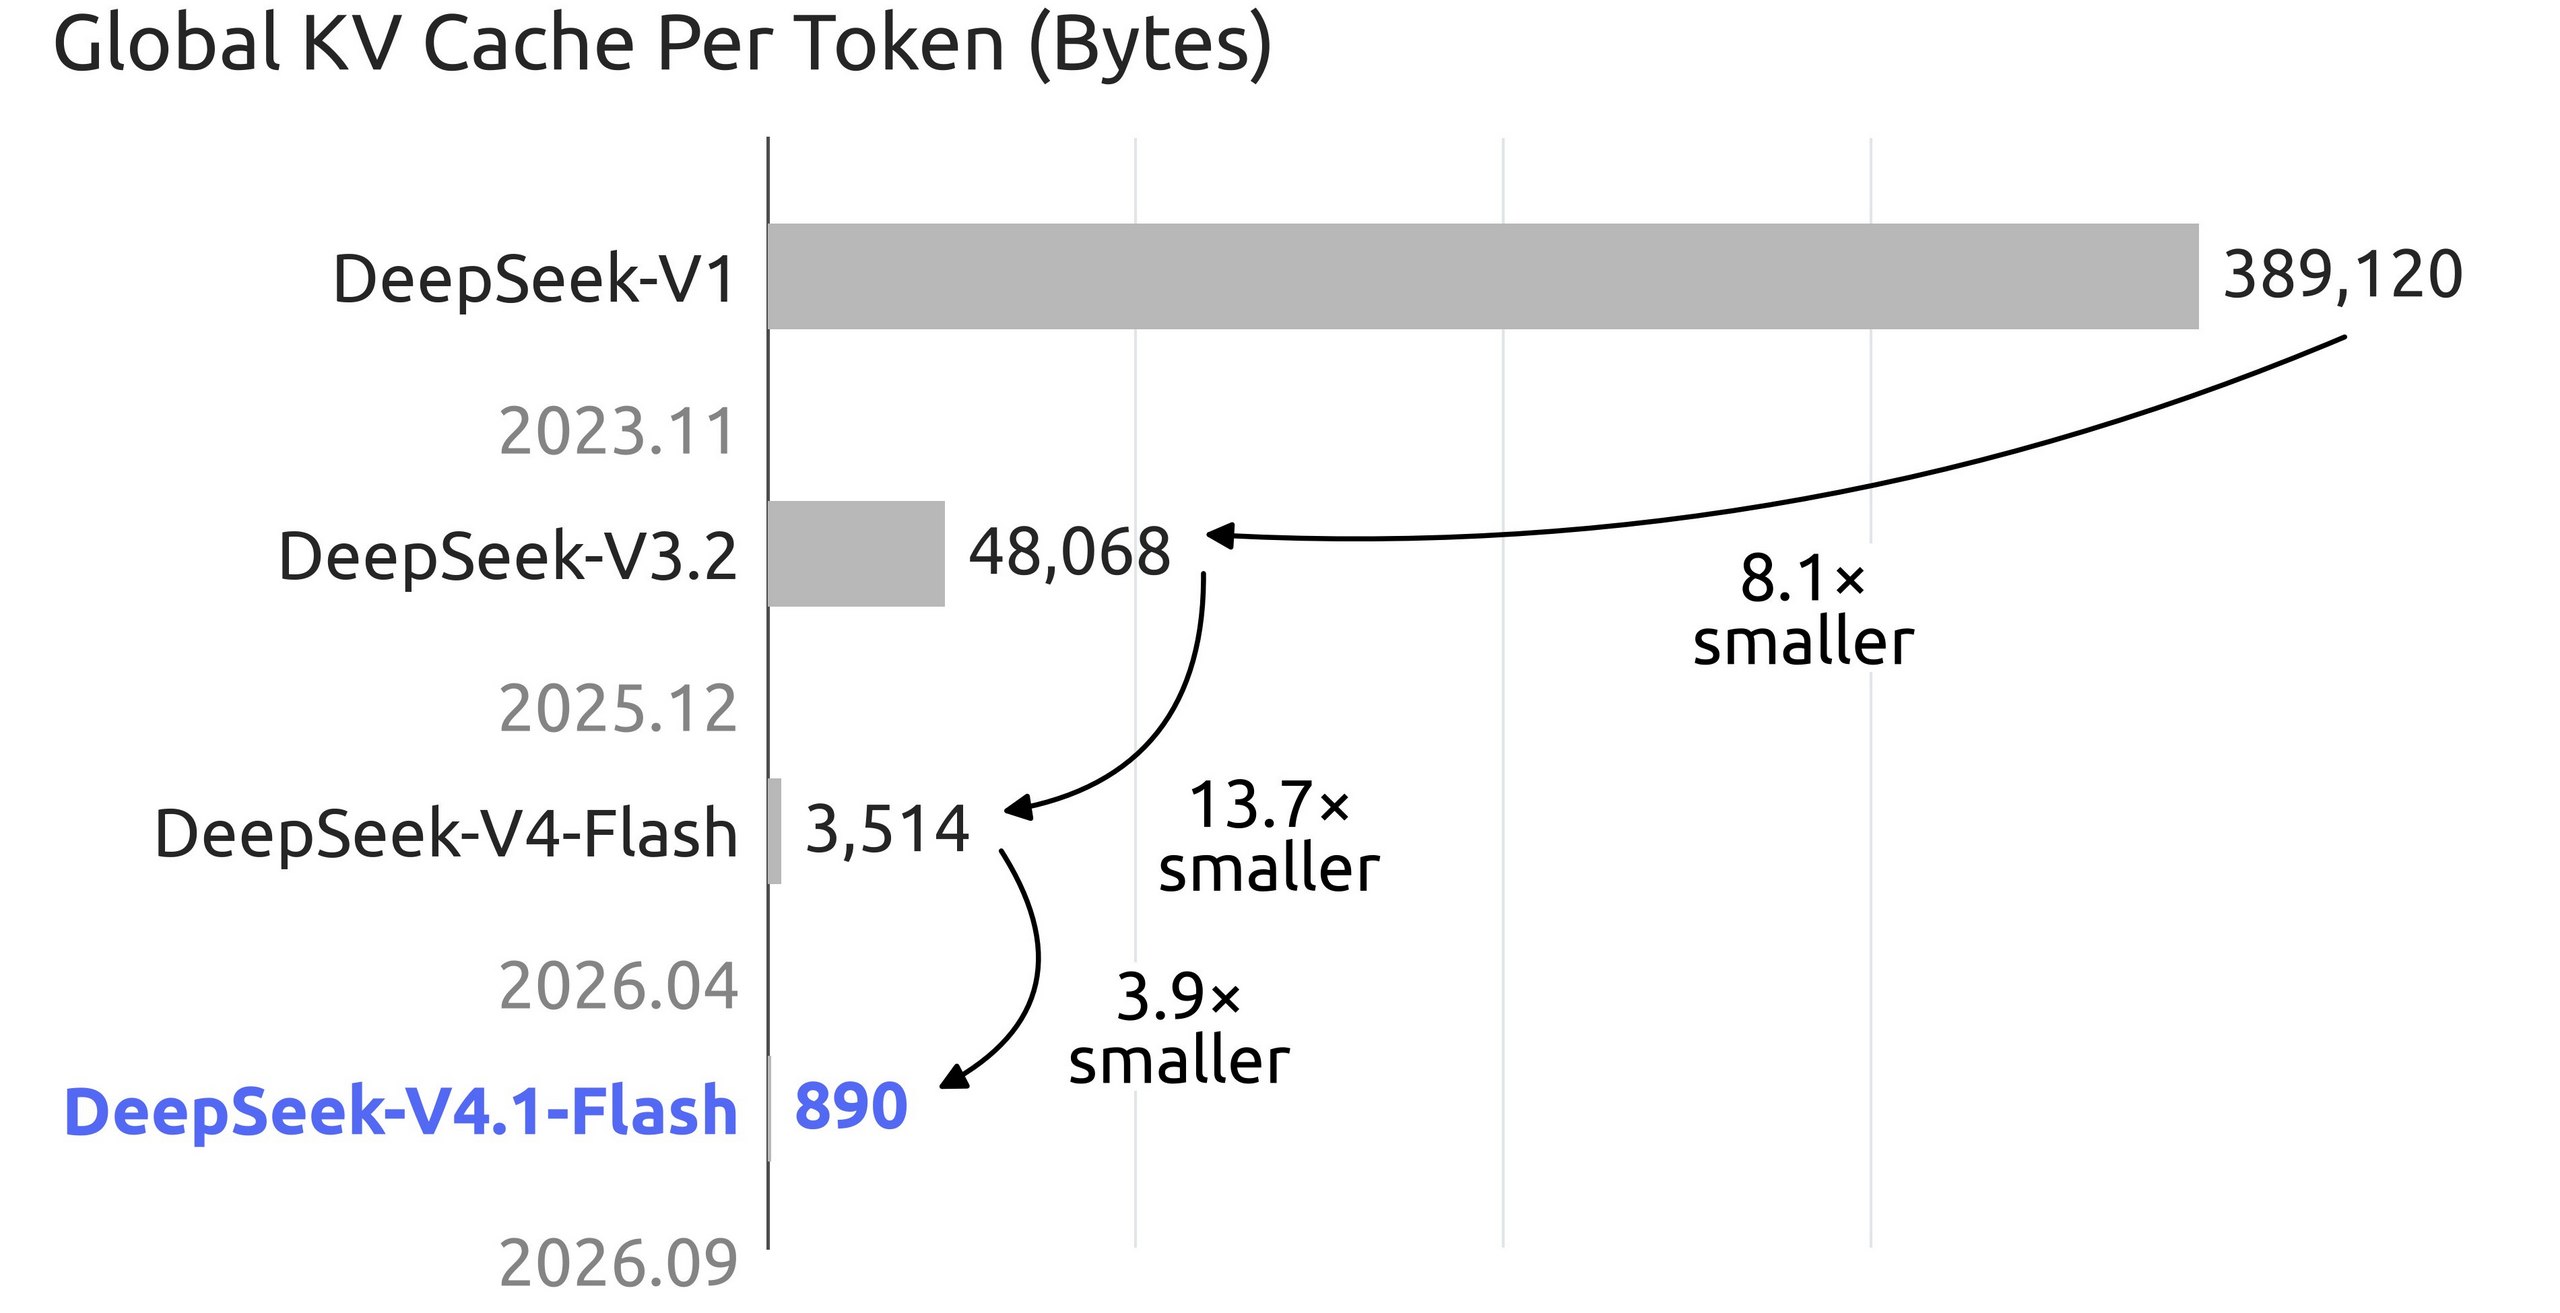
DeepSeek announced V4.1-Flash, featuring a smaller KV cache that requires 1/4 the HBM and 1/8 the SSD storage of the previous generation, significantly reducing…

Agents & automation
#KV Cache#V4.1-Flash#DeepSeek#AI Optimization#Cost Reduction#AI Agents

Related ecosystem entities

Observed across 3 sources

1 editorial report · 2 verified social mentions. The most authoritative report leads while later evidence completes the story.

Social corroboration

telegram

💾 Smaller KV cache. Bigger savings. Compared with the previous generation, V4.1-Flash’s KV cache needs just: 🔹 1/4 the HBM 🔹 1/8 the SSD storage Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly.

Open mention
telegram

🐋 DeepSeek just made its AI architecture much cheaper DeepSeek has introduced V4.1-Flash, a new multimodal model designed to deliver more intelligence while using dramatically less compute and memory. The model has 552B parameters, but only 8B are active for input and 16B for output thanks to a new Causal Encoder–Decoder architecture. DeepSeek says its combination of new pre-training and large-scale RL can outperform even its flagship V4-Pro on several benchmarks. The bigger breakthrough may be efficiency. V4.1-Flash uses just 1/4 of the HBM and 1/8 of the SSD storage needed for its previous-generation KV cache. That matters a lot for AI agents, where cached context can become a major part of inference costs. DeepSeek is also cutting prices, with off-peak rates set at 50% of peak pricing. Source. @aipost 🏴

Open mention
BTC—
SYNCING
ETH—
SYNCING
NVDA—
SYNCING
MSFT—
SYNCING